Linear Readability Does Not Guarantee Writability: Evidence from Controlled Counterfactual Recomposition
能够准确读出模型内部状态的线性方向,是否也能在状态改变时有效引导模型的决策?
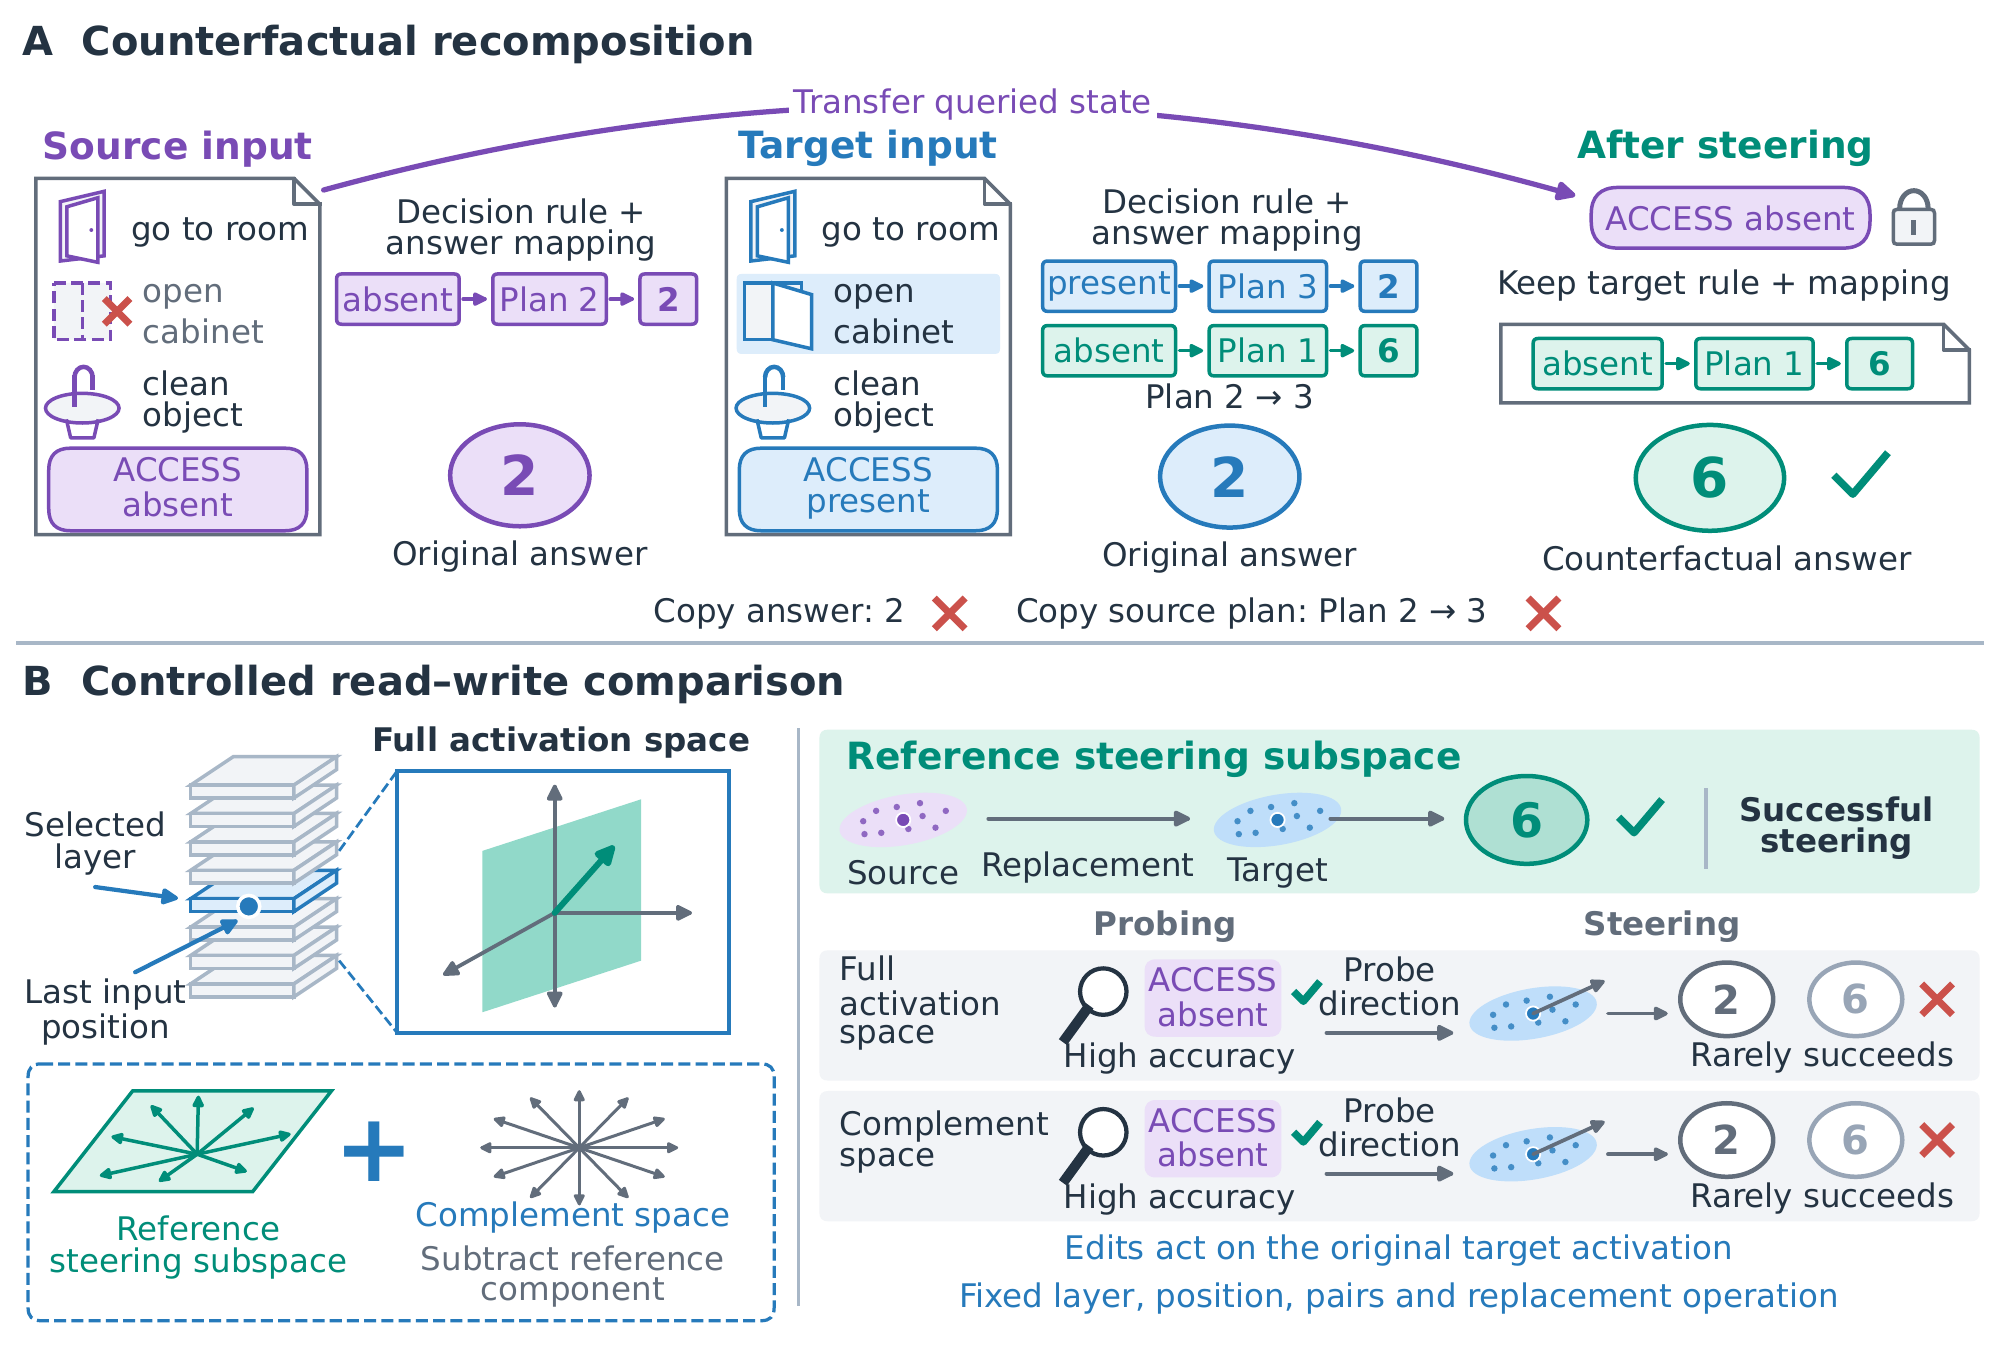
图 1.受控反事实重组与读写对比。A:将源状态与目标规则、答案映射组合后,应得到答案 6;复制原答案或源计划则分别得到 2 或 3。B:经过验证的引导子空间之外仍保留可读的状态信息,但在相同干预条件下,直接探针方向很少能实现所需的重计算。
查看原图 ↗摘要
Linear probing reveals information encoded in large language models, but whether probe-derived directions can reliably steer model decisions remains unclear. To investigate this question, we carefully design a controlled experiment on tasks constructed from ALFWorld and WebShop trajectories, whose action lists allow us to define explicit state changes and determine the corresponding answers. In the experiments, we combine the source input’s queried state with the target input’s decision rule and answer mapping, which we term counterfactual recomposition, to test whether steering supports the intended recomputation rather than merely copying an answer or source plan. Simultaneously, we learn and validate a reference steering subspace to ensure that steering can produce the required counterfactual answer at the selected location. This reference enables a controlled comparison with probe-derived steering in the complement space under fixed intervention conditions. Across four models and both environments, probing accuracy remains near-perfect in the complement space, while steering with direct probe directions, covariance-transformed directions, or combinations of multiple probe directions achieves near-zero counterfactual recomposition accuracy. These results reveal a critical finding: high readability alone does not guarantee writability through probe-derived interventions even with effective steering available, which provides valuable insight for developing reliable steering methods.
主要方法与贡献
- 基于 ALFWorld 与 WebShop 轨迹构造受控任务,将源输入的状态与目标输入的决策规则、答案映射组合,区分真正的反事实重计算与直接复制答案或源计划。
- 学习并验证参考引导子空间,确认所需的答案改变可以实现,再固定层、位置、样本对与替换操作,对比由线性探针得到的干预方向。
- 在四个模型、两个环境中发现:参考子空间的正交补空间仍保留近乎完美的线性可读性,但沿直接探针方向进行干预的反事实重组准确率接近零。
- 进一步检验协方差变换与多探针方向组合;这些方法在完整激活空间中的提升未能延续到补空间,说明高探针准确率本身不足以证明相应方向能够有效引导模型。